Guide to Figshare
Your guide to storing, sharing and managing data, code and methods in 缅北禁地鈥檚 repository
using your 缅北禁地 credentials. At the top of the screen, click ‘Upload’. You will need to select the most suitable item type from 'dataset', 'software', ‘data management plan’ or ‘workflow’. Other output types should be submitted via NUProfiles.
Before uploading your files, please ensure that you have the appropriate permissions or informed consent for publishing the data. If relevant, anonymise the data.
Files
‘Browse’ to upload your files, or drag and drop them in the box on the screen. You can add multiple files to one record. Click ‘Continue to metadata’. You can also continue without uploading files and proceed to filling the metadata fields first, while you and other colleagues are still working on the data. To ensure that the data can be used by a wide-range of researchers we recommend a README file is also created and uploaded alongside the other files. This will include study-level information about the context and design of the research and data-level documentation, including information about variables and relationships between different files.
Metadata
The purpose of adding metadata is to support discoverability and to maximise the reusability of the item. Each item should be a standalone output and include a link to all information necessary for interpretation and reuse.
- Add a title that describes the data. The title should differ from the publication title and will help make your items discoverable on search engines such as Google, and in your author profile. Avoid using underscores and file extensions in the title as it can reduce its discoverability. Ensure the title is meaningful for someone without prior knowledge of the item.
- Add additional authors. These should be the people who were involved in creating, processing or analysing the data deposited. 缅北禁地 researchers will appear as you type. Click on their name to add them. External collaborators can be included too. In the same author field, press ‘Enter’ after typing their name and add their ORCID and email address. Before doing this, please ensure you have their permission to add their details. The order of authors can be changed by clicking and dragging the names to the correct place. You can remove yourself as an author if you are uploading on behalf of someone else.
- Select subject categories. This is controlled vocabulary field that is intended to provide standard classification for research outputs. Choose all categories that apply for the item. The list of categories is fixed and based on the .
- Add keywords that are relevant to the deposited data. The keywords can be more specific than the categories and should be used to make the item more discoverable. Usually, we recommend that you use synonyms and alternative terms to those used in the title and item description. There is no upper limit of the number of keywords but remember to keep the keywords accurate and relevant. To increase interoperability of the item the keywords should be written in a formal and broadly applicable language. It is a free-text field, so special attention should be paid to the correct spelling of keywords. Misspelling keywords will decrease the findability of the item. Searches based on keywords are not case sensitive.
- Add a description for the deposited data. This is to provide potential future users with a clear understanding of what the data are. It will act as an abstract for the record. For someone interested in the item it can be informative to know the purpose of the item (e.g. why it was generated, or the value in sharing it). If file extensions are uncommon, the depositor should provide information about specific software needed to open the files and the version of the software, along with a URL or DOI to this software.
- Include the details of any funding grants received (ideally the grant refence number). When typing a grant number, the system will automatically search the database for the grant. If the information is found, a hyperlink will be generated to the Dimensions page.
- The ‘Related materials’ section allows you to link to related content (internal or external) to help describe the research. By using titles and DOIs, this section links to content such as pre-prints, publications, project websites, related datasets, collections and many more.
- Apply a licence to the data.
- NU Legacy ID: please ignore this field.
- Apply an embargo if required. This allows the data to be deposited, and a link created for inclusion in scholarly outputs, but to delay the access to the data. Please ensure that you make a note of the embargo expiry date, which is when the data will become publicly available. If you need to amend the embargo, please do so a few weeks before the expiry date and resubmit the dataset for review.
- 'Manage Identifiers' allows you to reserve a DOI. This will enable you to enhance the Data Access Statement or relevant research outputs.
- 'Edit timeline': if you are creating a record about data already published elsewhere, use the ‘First online date’ to specify when the data were published.
- Click 'Save changes'.
- When your data are ready to be published, click ‘Submit for review’ to notify colleagues in Library Research Services of your submission.
The Library Research Services team will review the deposited data and either approve and publish the item, or suggest edits.
Licensing your data
This is a mandatory field where a licence for the item is stated. A licence normally limits how the item can be reused and altered, in what context it can be used and how the creator should be credited. The appropriate licence can sometimes be specified by the funder, the publisher, or institutional policies. We recommend licensing data under an open licence that allows for wide reuse and suggest:
For all items apart from code and software:
- CC0
- CC BY 4.0
- CC BY-SA
- CC BY-ND
- CC BY-NC
- CC BY-NC-SA
- CC BY-NC-ND 4.0
For code and software:
- MIT
- Apache 2.0
- GPL 3.0 +
Data held elsewhere:
If you are registering a dataset archived elsewhere select the same licence that it has already been published under, as long as you have the permission to share it.
If it is a linking record to data held elsewhere, such as a metadata-only record, ensure that the licence is ‘Copyrighted’.
Figshare provide a , but you can get in touch with colleagues in Library Research Services if you have any questions.
Data held elsewhere
You can create a link to data that has been deposited elsewhere, such as funder specified or a discipline specific repository. Creating this link in the 缅北禁地 repository will increase the discovery of the data and can be used to form part of a collection or project. Where possible, the link should be a DOI or another type of persistent identifier to maintain the connection to the dataset.
Creating a metadata record
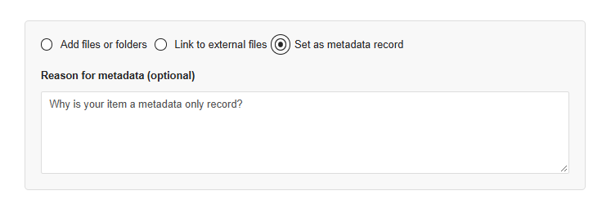
You can create a metadata-only record for data that require to be part of the catalogue, or on your researcher profile, but cannot be uploaded. This is suitable when the data are non-digital, or located in a different digital repository, or highly sensitive in nature.
Create a new item record or edit a record in the My Research and My Submissions area tab and tick the ‘Link to external files’ (and provide a link) or ‘Set as metadata record’ (and provide a reason).
Confidential data
You may want to make the data record findable but not openly accessible by making the data confidential. Consider the nature of the data and whether they can be uploaded to the repository, or whether a metadata record is more appropriate explaining how the data can be accessed under controlled conditions. For highly sensitive data (including identifiable NHS patient data) a metadata record is more appropriate.
When creating a confidential data record, providing a reason and noting if the data can ever be shared will help the data curation process, and long-term transparency.
Embargoes
If there is a reason why the data should not be made publicly available as soon as they are approved by reviewers in Library Research Service, you can apply an embargo. This allows the data to be deposited, and an identifier (DOI) created for inclusion in scholarly outputs, but to delay access to the data.
There are two options when applying an embargo:
- file level: the metadata record will be publicly visible, but the files will be hidden.
- entire item: the metadata record and data will not be visible until the embargo expiry date. This limits the discoverability of the data record and DOIs will not resolve to such records until after the embargo has lapsed.
We advice against the use of permanent embargoes. If you wish to embargo the data permanently, we recommend that you create a metadata-only record, explaining whether the data can ever be accessed and how. We recommend not setting embargoes longer than one year. If you plan to only publish the data in more than one year, you may consider not depositing them yet.
When you apply an embargo, you will be responsible for managing it. Please make a note of the embargo expiry date, as when the date is reached the embargo will expire without notice. Please .
Additional repository storage space
Every 缅北禁地 member involved in research has a small amount of storage space allocated. This allows most researchers to get started and use the repository to share meaningful data from their projects.
We appreciate that for some, the storage space will not be sufficient. If that is the case for you, please contact us at lrs@ncl.ac.uk to request additional storage. To support your request, please tell us:
- the reason why you would like to share your data. Do they have reuse value?
- what file types you are using.
- whether you considered compressing the files (without reducing data quality or value).
- if alternative file formats are an option.
Generating private links
Before publishing your data openly (while not submitted for review, or still under review, or under embargo), you can create a private link to share with collaborators or peer-reviewers. To create the link, upload the data and then click ‘Share with private link’ and save changes.
You can also reserve a digital object identifier (DOI) for the archived data, which is useful for the peer-reviewed journal publishing process. Rather than publishing the data ahead of the related article, you can reserve the DOI to create the data access statement for inclusion in the paper and then publish the data once your manuscript has been accepted.
Linking data.ncl to your ORCiD
The 缅北禁地 repository provides an ORCID integration that, once connected, will allow you to push all of your public items from the 缅北禁地 repository to ORCID.
To push all of your public items from the 缅北禁地 repository to ORCID you need to ensure DataCite is authorised on your ORCID account. DataCite are responsible for issuing the DOIs to data in the 缅北禁地 repository. Once authorised, your public the 缅北禁地 repository items will be displayed in the work section of your ORCID profile.
Step 1: Sign in at
Step 2: Sign in with your ORCID
Step 3: Authorise:
- Scroll down to the Works section and click +Add works
- Select Search & link, you’ll be presented with the services you can link to
- Select
You will be presented with a permissions form. Upon reviewing the Privacy Policy, tick the box alongside 'Allow this permission until I revoke it' and select Authorise.
You will then be taken to your DataCite settings page. To check the authorisation has worked successfully head back to ORCiD and to your Account Settings tab. ORCiD should now be listed as a Trusted organisation.
Furthermore, you can set up a DataCite profile (if you don't already have one) and then give DataCite permission to automatically update your ORCID record. You only have to do that once and DataCite will keep on updating your ORCID record every time they mint a DOI, where your ORCID iD is included in the metadata. See and click on ORCID Auto-Update once you have a profile set up. In this way, you do not have to keep manually adding Figshare items to your ORCID account. This is especially useful when you have a lot of data.
Step 4: Sync your ORCiD to your 缅北禁地 repository profile:
Go to your profile page on your account and click on ‘Connect to ORCID’ and enable syncing with your ORCiD.
Step 5: Sign in to ORCID.
Step 6: Authorise.
Step 7: Your ORCID is now synced.
Collections
Collections are ways of collating published data items with a shared theme within the repository, and can be assigned a DOI. To create a collection:
- On the repository landing page, click ‘My Research’ at the top-right of the screen, then select ‘Collections’.
- click 'Create new’.
- Complete all the relevant metadata fields.
- Click ‘Reserve DOI’.
Once you've created the collection, click ‘My Research’ again, select ‘Collections’, and you should see the newly created collection. Click its title. Select ‘Add content’. Use the filter on the left to choose whether you will add items owned by you (potentially still unpublished), or items already public in the repository (not necessarily owned by you). Once you added them, click ‘See items in collection’. At the top-right, there is a ‘Manage collection’ button. The ‘Publish’ button will become available once all the items you added to your collection become public. It will allow you to publish the collection.
Once you’ve published a collection, it’s permanent.
Projects
Projects are a collaborative space to prepare data for deposit. You can upload data that are in progress and users within and beyond 缅北禁地 can contribute. Please note, if you would like to group multiple datasets from one project, and publish them, we recommend that you use the Collections function, rather than Projects.
To create a project:
- Go to the ‘Projects’ tab under ‘My Research’.
- click 'Create new’.
- Complete all the relevant metadata fields.
Individual projects
- everyone uses their own quota and account storage.
- people take their data records with them if they leave the project.
- items are created using the metadata schema of the submitter.
- items published by users from outside the organisation don’t have to go through review.
Group projects
- submitters’ quota will not be used, as storage allocation comes directly from the project.
- all work is stored on institutional storage and remains within the project space if people leave.
- contributors must adopt the metadata schema of the project owner.
- items published by users from outside the organisation must be reviewed.
When you edit a project, add users by selecting ‘Invite’ on the right side of the screen. Users can either be collaborators or viewers. Collaborators can comment on the project and the data within it and upload items, while viewers can only view the data. To make the project public, you must first make at least one item public within the project.
Please note: The project owner, collaborators, and viewers cannot edit another uploader’s items. Items must be downloaded, edited, and re-uploaded to the project.
Log in, upload and describe your data
data.ncl licencing your data, embargoes and confidentiality
data.ncl Collections
data.ncl Projects